A dashboard can expose a sensitive customer segment just as easily as a breached source system can. For regulated organizations, knowing how to secure analytics pipelines is therefore not a narrow infrastructure task. It is a discipline for preserving the confidentiality, integrity, availability, and evidentiary value of data as it moves from operational systems into reports, models, and decisions.
Analytics pipelines create value by connecting systems that were not designed together: core banking platforms, claims applications, ERP systems, government registries, data lakehouses, business intelligence tools, and AI workloads. Each connection introduces a trust boundary. Security must follow the data through those boundaries rather than stop at the network perimeter.
Start with the pipeline, not the platform
A common failure is treating the data platform as secure because it has encryption, role-based access control, and a compliant cloud tenancy. Those capabilities matter, but they do not secure a pipeline whose service accounts have excessive privileges, whose transformations expose raw data in temporary tables, or whose reports can be exported without oversight.
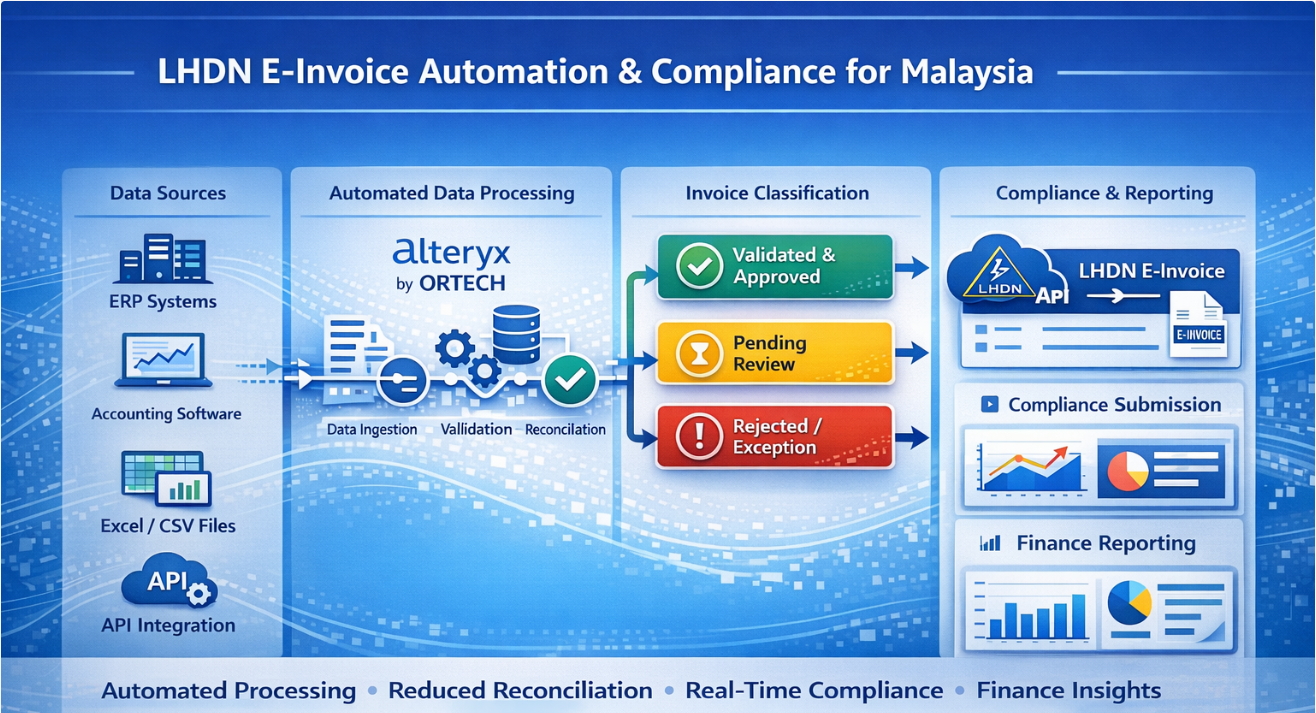
Map the full data flow before selecting controls. This should include ingestion endpoints, storage layers, transformation jobs, orchestration services, semantic models, consumption tools, machine learning feature sets, and downstream extracts. It should also identify where data is copied, cached, masked, aggregated, or retained.
For each stage, assign a business owner, technical owner, data classification, approved purpose, and control requirement. This turns security from a collection of technical settings into an operating model that risk, compliance, data, and platform teams can govern together.
The depth of this exercise depends on the institution. A bank handling customer financial records will require tighter segregation and audit evidence than an internal operational reporting pipeline. Yet both need clarity on who can access data, why they need it, and what happens when a pipeline fails or behaves unexpectedly.
How to secure analytics pipelines with layered controls
No single control can protect an analytics estate. Effective protection comes from layers that limit what an attacker, an internal user, or a faulty process can reach.
Establish a data classification and policy model
Security decisions should be driven by data sensitivity, not by the tool in use. Define classifications that are meaningful to the organization, such as public, internal, confidential, restricted, and regulated. Then translate those classifications into enforceable handling policies.
A restricted customer identifier may require tokenization before it reaches a shared analytics zone. A confidential financial metric may be visible only to approved finance roles. A dataset intended for AI experimentation may need de-identification and a separate approval path before use.
Policies must apply consistently across storage, transformation, and consumption. If a sensitive field is masked in a dashboard but remains accessible in an intermediate table, the dashboard control provides only partial protection. Modern governance should preserve tags, lineage, and policy decisions as data moves across the lakehouse.
Enforce least privilege for people and workloads
Analytics environments often accumulate broad permissions because teams need to move quickly. Over time, generic administrator roles, shared credentials, and long-lived access become a significant operational risk.
Use role-based access control for stable job functions and attribute-based policies where access must reflect context, such as business unit, data residency, or clearance level. Separate platform administration from data access. A data engineer who can operate a pipeline does not automatically need permission to read all customer records processed by it.
Workloads require the same discipline. Every ingestion connector, orchestration job, notebook, and reporting service should use a distinct machine identity with only the permissions required for its task. Short-lived credentials are preferable to static keys. Secrets should be managed centrally and injected at runtime, never embedded in source code, configuration files, or notebooks.
Privileged access should be time-bound, approved, and logged. This is particularly important when support teams need access to production environments. Emergency access may be necessary, but it should be exceptional, traceable, and reviewed afterward.
Protect data in motion, at rest, and in use
Encryption in transit and at rest is a baseline requirement, not the final control. Organizations should also consider where encryption keys are held, who can administer them, and whether the key-management design supports sovereignty, contractual, and regulatory obligations.
Data in use demands additional safeguards. Tokenization, dynamic masking, row-level security, column-level security, and secure data-sharing patterns can reduce exposure without blocking legitimate analysis. The right combination depends on the use case. A fraud investigation team may need access to identifiable transaction detail, while a product analytics team may only need pseudonymized behavior patterns.
Avoid relying on copies as a security strategy. Creating a separate extract for every team often multiplies the number of locations that require protection and retention management. A governed semantic layer or controlled sharing mechanism can give users the information they need while keeping the most sensitive detail within a managed environment.
Secure code, configuration, and change delivery
Pipeline security is also software security. Transformations can introduce data leaks, incorrect entitlement logic, or hidden dependencies even when the underlying platform is well configured.
Treat analytics code, infrastructure definitions, and configuration as controlled assets. Require peer review for changes to transformations, access policies, data models, and orchestration workflows. Automated tests should validate not only data quality but also security expectations: whether a restricted column is masked, whether a job can access only its permitted schema, and whether a new table inherits the correct classification.
Production deployment should use controlled CI/CD processes with segregation of duties. The person approving a change should not be the only person able to deploy it, especially for pipelines processing regulated data. Versioned infrastructure and policy-as-code also make it easier to demonstrate what changed, when it changed, and who authorized it.
Monitor behavior, lineage, and control drift
A secure design can weaken quickly if controls drift. New data sources arrive, teams create experimental workspaces, permissions expand, and a temporary exception becomes permanent.
Logging should cover authentication events, privilege changes, data access, pipeline execution, configuration changes, and outbound transfers. Logs need to be retained, protected from alteration, and connected to a practical review process. Collecting events without defined ownership and response procedures creates little assurance.
Detection should focus on meaningful anomalies: an orchestration identity accessing an unusual domain, a sudden high-volume export, repeated failed access attempts, a pipeline writing to an unapproved location, or a sensitive dataset appearing outside its designated zone. Data lineage adds essential context by showing which reports, models, and downstream processes may be affected.
Periodic access reviews, configuration assessments, and control testing should be scheduled as operating activities rather than audit-week exercises. In a large enterprise, automation is necessary to identify stale accounts, overprivileged roles, untagged datasets, and unencrypted endpoints before they become incidents.
Design for recovery, not only prevention
Analytics pipelines influence credit decisions, regulatory reporting, public services, and executive planning. A security incident can therefore become an operational and decision-making incident. Recovery planning must address both system availability and data trust.
Maintain immutable or protected backups for critical datasets, pipeline definitions, metadata, and access configurations. Test restoration of a complete business process, not merely a database object. A restored dataset is of limited value if the orchestration logic, lineage records, key permissions, and validation rules cannot be recovered with it.
Define incident playbooks for compromised credentials, unauthorized data disclosure, corrupted transformations, ransomware, and third-party connector failure. The playbook should identify who can pause pipelines, revoke access, preserve evidence, notify stakeholders, and determine whether reports or models need to be withdrawn. For financial institutions and government agencies, these decisions often involve legal, compliance, and operational leaders as well as technical teams.
Make security measurable and governable
Executive oversight improves when pipeline security is expressed through operational measures rather than abstract assurances. Track the percentage of sensitive datasets classified, the number of privileged identities, time taken to revoke access, coverage of lineage, policy exceptions, remediation aging, and recovery-test outcomes.
These metrics reveal trade-offs. Stronger controls may introduce friction for analysts, while broad self-service access can increase exposure. The objective is not to eliminate all friction. It is to make access proportionate, accountable, and reliable enough that business teams can use trusted data without creating unmanaged risk.
For organizations modernizing across cloud, on-premises, and hybrid environments, consistency matters more than uniformity. Controls may be implemented differently across platforms, but the governing principles, ownership model, evidence requirements, and risk thresholds should remain consistent. This is where analytics engineering and data governance need to operate as one discipline.
Secure analytics pipelines create a foundation for faster decisions because leaders can act on information that is not only available, but controlled, traceable, and fit for purpose. The most durable programs make security part of how data products are designed and operated, long before the next dashboard, model, or regulatory request puts that trust to the test.