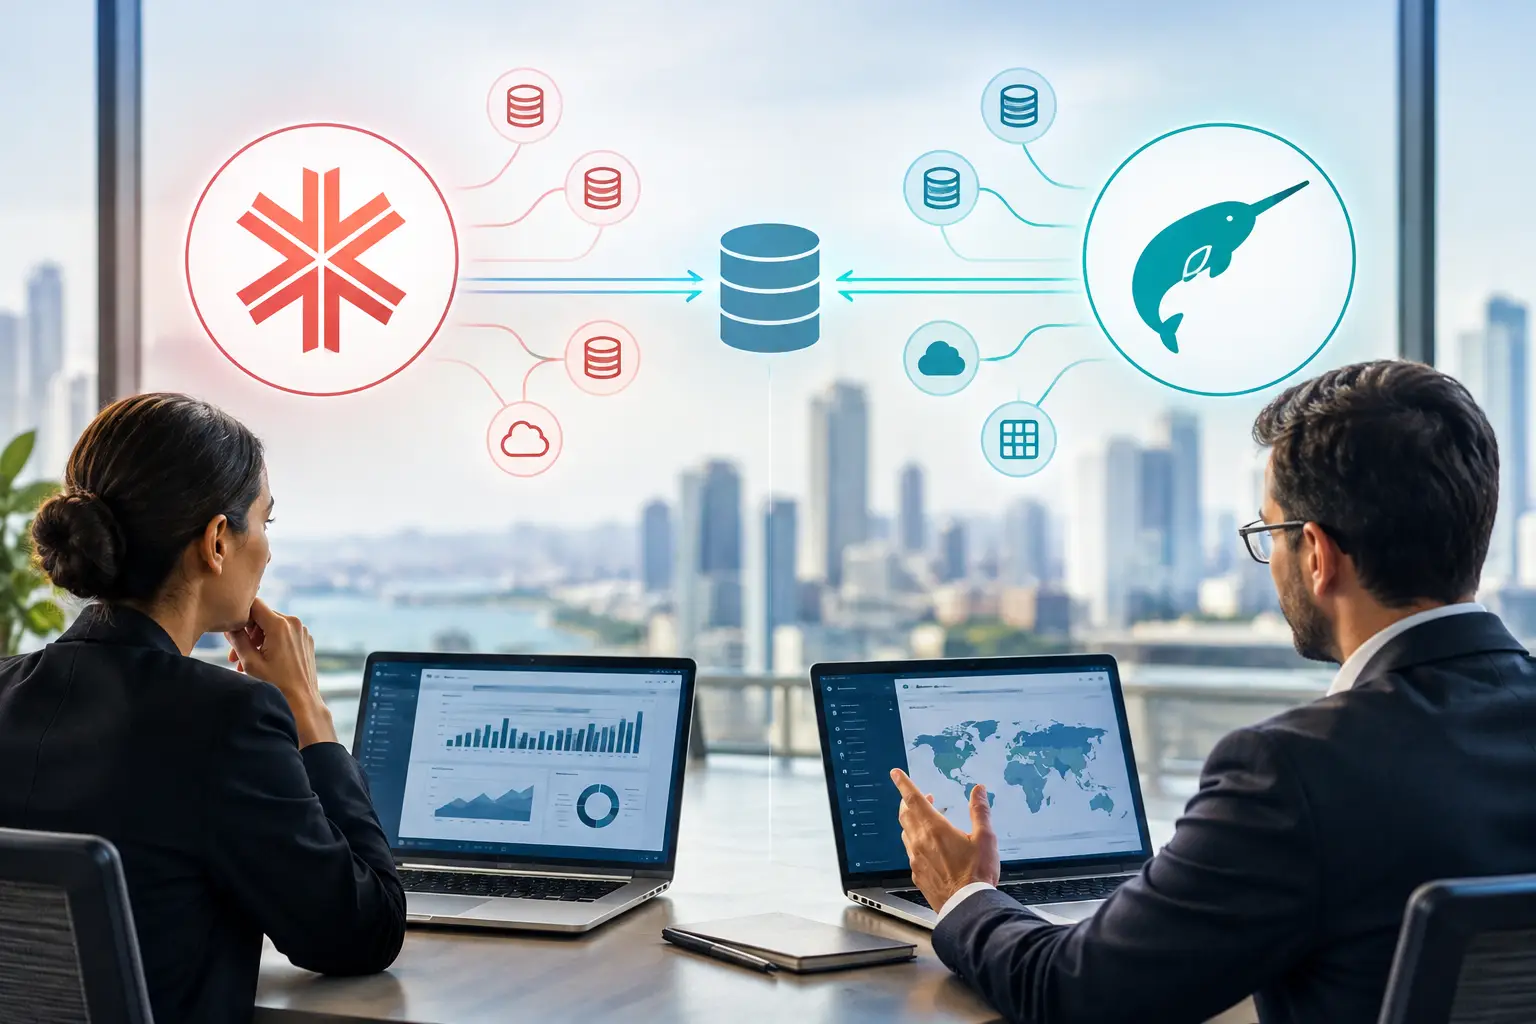
A query federation decision becomes consequential when a risk team needs to reconcile customer, transaction, and reference data across systems without creating another uncontrolled copy. In the Starburst versus Dremio query federation discussion, the central question is not which platform can connect to more sources. Both can query beyond a single database or lakehouse. The real decision is where an enterprise wants its data gravity, semantic control, performance engineering, and governance operating model to sit.
For regulated institutions and large public-sector organizations, federation is rarely an isolated technology choice. It influences how quickly teams can deliver analytics, whether sensitive data stays within approved boundaries, how consistently metrics are defined, and how practical an AI-ready data foundation will be to operate over time.
Starburst versus Dremio query federation: the architectural distinction
Starburst is commonly evaluated as a federation-first query layer. Built around the Trino query engine, it is intended to provide SQL access across heterogeneous systems, including data lakes, cloud warehouses, relational databases, and selected operational platforms. Its value is most apparent when valuable data remains distributed for sound reasons: regulatory boundaries, system ownership, migration sequencing, latency requirements, or the cost and risk of moving sensitive records.
Dremio also provides access to multiple data sources, but its strategic center of gravity is typically the lakehouse. It is designed to make data in open table formats, particularly Apache Iceberg-based environments, easier to govern, accelerate, and serve to analytical users. Its query capabilities can reach external sources, yet many organizations realize the strongest long-term benefit when they use Dremio to establish a curated, high-performance data layer rather than rely indefinitely on broad cross-system queries.
This distinction matters. Starburst often suits organizations that need to make distributed data usable now, while maintaining source-system autonomy. Dremio often suits organizations consolidating analytical workloads around an open lakehouse and seeking a managed path from raw data to governed consumption. Neither approach is automatically superior. The appropriate choice follows the target operating model.
Federation does not eliminate data architecture
Query federation can reduce unnecessary data replication, but it does not make data movement, modeling, or quality management disappear. A federated query that joins a large transaction table in one environment with customer attributes in another still has to move intermediate results somewhere. Network latency, source concurrency limits, inconsistent formats, and uneven partitioning can quickly turn an elegant architecture diagram into an unreliable reporting experience.
The critical technical capability is pushdown: the ability to execute filters, aggregations, and other work as close to the source data as possible. Both platforms can take advantage of source-specific capabilities, but the result depends on the connector, source technology, query pattern, and permissions. Enterprise teams should test the actual workloads they expect to run, not generic benchmark queries.
For example, a bank may need analysts to combine sanctioned-party screening data held in a controlled operational store with curated transaction history in a lakehouse. Federation can support investigation workflows without first copying every sensitive record. That does not mean a daily enterprise risk dashboard should execute a large cross-source join from scratch at 8:00 a.m. Each workload needs a deliberate serving pattern: federate for timely access, materialize for repeated high-volume consumption, or publish a curated data product when the business definition has stabilized.
Where Starburst is usually strongest
Starburst is a strong fit when the organization has a durable multi-platform reality. This is common after acquisitions, during phased cloud modernization, or where country, agency, and business-unit systems cannot be consolidated quickly. It provides a way to establish a common SQL access layer while modernization continues.
Its federation-oriented model can also support data sovereignty objectives. Rather than centralizing all information into one platform before it can be analyzed, teams can leave approved data in its authorized domain and expose only governed views or permitted columns. This can be useful where personally identifiable information, financial records, or classified government data require different controls.
The trade-off is operational discipline. A federated layer depends on source systems being available, performant, and properly governed. It also requires architects to define which queries are acceptable against operational systems, establish workload controls, and prevent convenience from becoming uncontrolled dependency. Starburst can simplify access, but it should not become a reason to run unbounded analytical workloads against production applications.
Where Dremio is usually strongest
Dremio is often most compelling when an enterprise is standardizing on a lakehouse as its primary analytical foundation. In this model, data is landed, transformed, cataloged, and served through open table formats with consistent access patterns. Dremio can help create a logical consumption layer over that foundation, supported by semantic definitions and query acceleration mechanisms such as reflections.
That orientation is particularly valuable for recurring analytical workloads. Finance, risk, customer analytics, and operational planning teams generally need trusted metrics that perform predictably across many users and tools. A lakehouse-centered platform encourages teams to convert repeatedly used data into governed, reusable datasets instead of repeatedly reconstructing logic across distributed source systems.
The trade-off is that Dremio does not remove the need to design ingestion, transformation, and data product lifecycles. If the organization must frequently join live data across many independently owned operational platforms, a lakehouse-first approach may require additional engineering or carefully selected federation patterns. It is most effective when leadership has made a credible commitment to a common analytical data foundation.
Performance is a workload design issue
Performance evaluations should move beyond a simple question of query speed. The more useful question is: which platform can meet the service expectation for each workload while preserving control over cost, source impact, and data freshness?
Starburst may be well suited to exploratory access and cross-domain investigation, particularly when queries can push computation to source systems and avoid excessive data transfer. Dremio may be advantageous for repeatable analytics over curated lakehouse data, where acceleration and optimized table design can improve consistency at scale.
In either case, the heaviest recurring workloads should be identified early. These frequently include regulatory reporting, month-end finance, fraud monitoring, executive dashboards, and feature preparation for machine learning. A platform evaluation should measure concurrent users, data volumes, query complexity, refresh frequency, source-system impact, and recovery behavior. A fast demonstration on a limited dataset is not evidence of enterprise readiness.
Governance must be designed across the query path
Federation broadens access, which makes governance more demanding rather than less important. A user may query one logical view while the underlying data comes from several platforms with different security models, metadata quality, and retention requirements. Without a clear control model, the enterprise can lose visibility into who accessed what, which policy applied, and whether a metric has the same meaning in every report.
A sound design establishes consistent identity and authorization, applies row- and column-level controls where required, records audit activity, and assigns ownership for business definitions. It should also distinguish between discovery access and certified data products. A catalog entry alone is not a trusted dataset; teams need lineage, quality expectations, stewardship, and a process for managing changes.
For AI-ready data programs, this is especially relevant. Models and decision applications need traceable, well-defined inputs. Federating inconsistent operational data directly into analytical or AI workflows may be appropriate for a narrow, time-sensitive use case, but it is not a substitute for governed feature, entity, and reference-data foundations.
A practical decision framework
The selection process should begin with the desired data architecture three years from now, not only the connectivity gap visible today. Leaders should assess four areas together:
- Data distribution: Are critical datasets expected to remain in multiple platforms, or is the organization moving toward a lakehouse as the primary analytical system?
- Workload profile: Is the priority live cross-domain investigation, repeatable high-concurrency analytics, or a deliberate mix of both?
- Governance model: Can policies, metadata, lineage, and access controls be enforced consistently across the full query path?
- Operating capability: Does the organization have the engineering capacity to manage connectors, workload controls, table optimization, semantic definitions, and platform adoption?
A focused proof of value should use representative data domains and realistic security constraints. It should include difficult queries, source outages, concurrent demand, policy enforcement, and the workflows used by analysts and data engineers. The goal is not to prove that a query runs. It is to determine whether the platform supports a sustainable operating model.
For many enterprises, the answer will not be exclusively Starburst or Dremio. A federation layer can provide controlled access during modernization, while a lakehouse platform becomes the strategic home for curated, reusable data products. The strongest architecture is often one that makes this transition intentional: federate where data must remain distributed, materialize where demand is repeatable, and govern both through a common enterprise data strategy.
The useful closing question for technology leaders is not which query engine wins a feature checklist. It is which design helps the organization turn fragmented data into trusted intelligence without creating the next generation of complexity.